Global Observation Archive · GOA-00047
The Human Data Acquisition Shift
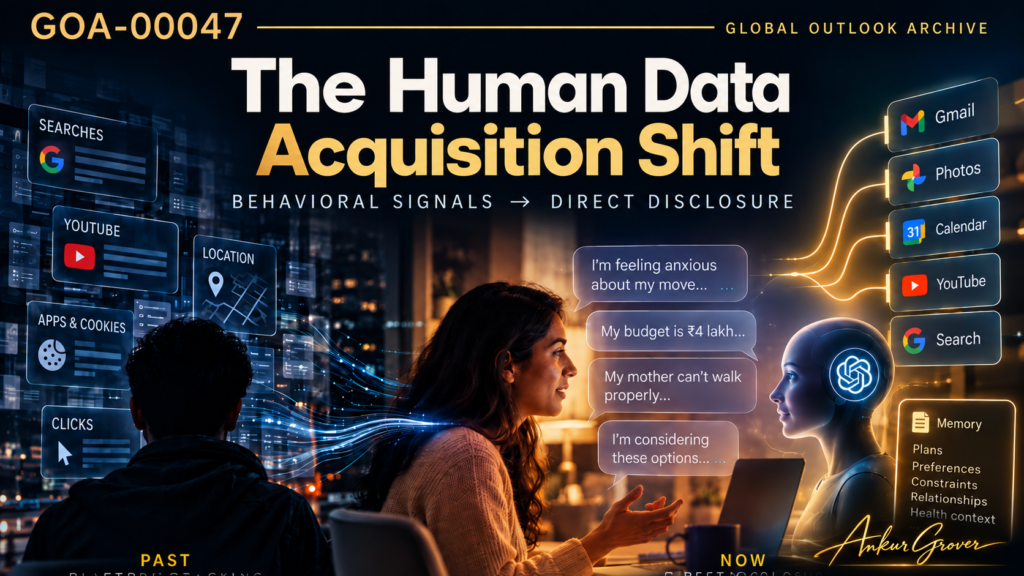
Conversational AI will scale direct acquisition of high-context human information
Google और Meta ने दशकों में इंसानी digital behaviour की विशाल data layer बनाई। Conversational AI ने कुछ ही वर्षों में उसके साथ एक अलग surface जोड़ दिया: इंसान अपने goals, plans, constraints और decision context सीधे machine को बताने लगा। 2026 में यह surface मौजूद है। GOA-00047 की prediction इसके अस्तित्व पर नहीं, इसके scale पर है।
Older digital systems learned about people largely from what they did: searches, clicks, views, purchases. Conversational AI adds a second route: what people tell the machine about themselves. This entry records that the route already exists, and forecasts that by 2031 the volume of high-context information people disclose through it will at least double per user.
1. Scope of the claim
This entry is about data acquisition: how high-context personal information enters AI systems. It is not about how operators later use that information, and it makes no claim about persuasion or behavioural influence. Those questions belong to a separate forecast.
In this entry, acquisition means information an AI service receives because the user communicates it, accesses through a connection the user has enabled, or persists through a memory feature the user has enabled. The word does not imply unauthorised or unlawful collection by any operator.
What GOA-00047 does not claim
- That AI systems hold more total data than Google or Meta.
- That earlier platforms relied only on passive tracking; they also received posts, messages and other user-provided content.
- That connected-app data is a new type of information.
- That automatic memory means the absence of user permission.
- That conversation reveals every attribute better than search or video history.
- That AI knows a person’s true motives.
2. The two-axis model
Two questions must stay separate: what kind of information something is, and by which route it reached the AI. Mixing them is the most common error in this debate.
| Axis A · type of information | Axis B · route into the AI |
|---|---|
| Directly stated context: facts the person explicitly says, e.g. “my total budget is ₹4 lakh” | Direct conversational disclosure: the person types or speaks it |
| Behavioural information: searches, watch history, clicks, purchases | Platform-native activity record: generated by ordinary use of a service |
| Repository content: email, calendar, documents, photos | User-authorised connected access: the person enables a link to another source |
| System-derived representation: a memory or profile entry built from material the system already had; a derivative, not a new fact | System-derived persistence: the system condenses available context into a stored representation |
A YouTube watch history reached through an authorised AI connection is still behavioural information. Only its route has changed. The only genuinely new source tracked here is direct conversational disclosure.
3. Founding evidence
All evidence below predates the observation date or describes conditions existing on it. Under the archive’s standing rule it is founding evidence, not validation.
3.1 Disclosure in conversation logs
Zaman and Garimella (May 2026) studied complete ChatGPT histories donated by consenting users in Brazil, India, Nigeria and Pakistan. On the full donated corpus of 1,242,109 user messages, before any cohort filtering, 34.5% of messages were assigned to a twenty-category personal-information taxonomy, and the median user first revealed identifying content within the first 14% of their history.
34.5% is not this entry’s baseline. The classifier was instructed to treat whatever a user asks about as being about the user unless stated otherwise, so every question could count as implicit disclosure. It measures broad personal-information signal, not directly stated high-context facts, and it was not computed on the later 1,057-user analytic cohort.
3.2 The same people across different surfaces
For 212 Indian participants the same study held four parallel streams: ChatGPT history, Google Search, YouTube Search and YouTube Watch. Running one inference protocol on each, no surface dominated. ChatGPT logs were strongest for age, education and voting preference; search-based streams were stronger for gender, religion and income; YouTube Watch was weakest throughout. The authors describe conversation as a comparable profiling surface with a different content emphasis, not a more invasive one.
This matched-user design is the methodological template for Gate C. The same study also found that inference errors concentrated on women in technical work, older users with contemporary skills and Global South technology professionals, which is why this entry does not use model inference as its primary measure.
3.3 System-derived persistence
Dash et al., in the peer-reviewed proceedings of the ACM Web Conference 2026, analysed 2,050 memory entries from 80 ChatGPT users and reported that 96% were created by the system rather than initiated by the user.
Zaman and Hoque (September 2026 preprint) audited 7,051 memory entries from 766 users. 4.64% were classified as explicit user commands; the remaining 95.36% formed a residual category of updates not detected as explicit commands by a multilingual keyword lexicon with fuzzy matching at an 80% similarity threshold. That figure is a methodological residual, not a measurement of consent.
Architecture limitation, recorded now. The Zaman–Hoque audit covers ChatGPT’s legacy saved-memory system, not the rebuilt memory architecture OpenAI introduced in June 2026. The authors report that by September 2026 legacy entries were no longer the default and that current data exports may not expose memory entries. Future audits may therefore need different methods; Gate B provides for this in advance.
3.4 Connected access and background memory as product features
Google’s Personal Intelligence, launched in India on 14 April 2026, can connect Gmail, Photos, YouTube and Search. Google states the connections are off by default and chosen by the user. OpenAI describes a background “dreaming” process, first added in April 2025 and rebuilt in June 2026, that synthesises memory from conversation history without an explicit save request for each item. Both are documented, user-facing product mechanisms.
4. Definitions
High-context fact
An explicitly stated, person-specific proposition about at least one of these nine categories: a goal; a future plan; a decision under consideration; a resource or budget constraint; work or project context; a relationship relevant to a decision; a decision-relevant preference; an explicitly stated reason or motive; a constraint on a future action.
Identifiers alone do not qualify. A name, phone number, IP address or city can be personal information without being a high-context fact.
Fact unit and observation window
A fact is counted once per user per 90-day window, however often it is repeated. A user is active in a window if they send more than ten messages in it, matching the minimum-history floor used in the founding study.
5. Forecast and review protocol
5.1 Core forecast
By 31 December 2031, the number of high-context facts that active users directly disclose to general-purpose conversational AI per 90-day window will be at least twice the September 2026 baseline, and conversation will remain a surface carrying explicit personal context not duplicated in the same people’s behavioural records.
5.2 Baseline rule
- Baseline window: 90 consecutive days ending on or before 24 September 2026.
- Follow-up window: 90 consecutive days beginning on or after 24 September 2029.
- The same taxonomy, fact unit and coding rules apply to both. A study using an improved method must apply it to the baseline as well.
- Coders must not know which period a record comes from. The baseline result must be publicly timestamped and archived before any follow-up analysis begins.
- The 34.5% figure can never substitute for the baseline.
5.3 Gate A · scale growth (the forecast)
Primary design: within-person panel. At least 1,000 consenting users active in both windows, from India and at least two further national markets, with at least 150 users per market. Cross-sectional comparison of different cohorts (at least 2,000 users per period) is secondary and cannot decide the gate.
| Result | Gate A state |
|---|---|
| Lower CI bound ≥ 2.0 and median-based ratio ≥ 2.0 | PASSED |
| Upper CI bound < 2.0 | FALSIFIED |
| Interval contains 2.0 | INCONCLUSIVE |
Results must also be reported by user tenure (how long each person has used the service), but the verdict rests on the pooled panel.
A survivorship sensitivity analysis must separately report users by baseline activity level and tenure, so that the 2× result cannot be explained solely by retaining unusually intensive long-term AI users.
If Gate A passes on the pooled panel but the point estimate for the combined lower two-thirds of users ranked by baseline activity is below 2.0, Gate A shall be recorded as PASSED (INTENSIVE-USER CONCENTRATED). Every public statement of the Gate A result and every overall verdict dependent on Gate A must carry this qualifier.
Why 2×. The surface already exists in 2026, so a modest rise would not show the structural scale-up this entry claims. Doubling is a deliberately demanding threshold fixed in advance; it is not derived from any founding figure.
Secondary breadth check. If the baseline median is six or fewer of the nine categories, the follow-up median should rise by at least one category. If the baseline median is already above six, this check is not assessed, because the taxonomy leaves too little room. It never decides the gate.
Channel-substitution rule. Better connected access may reduce what people need to type: an AI that reads a user’s email may no longer need to be told the budget. Where auditable, the study must also count high-context facts reaching the AI through user-authorised connections.
If direct disclosure is FALSIFIED but direct plus connected facts together meet the PASSED condition, the verdict is CHANNEL SUBSTITUTION: ORIGINAL FORECAST NOT VALIDATED. The original hypothesis is judged in its original form and is not reworded afterwards to count as a pass.
5.4 Gate B · system-derived persistence
At least two independent general-purpose AI systems must each be audited with at least 500 consenting users and 2,000 persistence events. Gate B passes if, for both systems, more than 50% of persisted updates occur without an item-specific instruction such as “remember this”. Because this is measured as a residual, the explicit-command detector must be checked by two human coders on a stratified sample of at least 200 events with Cohen’s κ ≥ 0.80.
The gate measures item-specific instruction against system-derived persistence. It does not measure consent, and the memory feature itself may have been enabled by the user.
Evidence access. A raw memory export is not required. Qualifying audits may use reproducible before-and-after snapshots of user-visible memory, controlled longitudinal test accounts, independently accessible logs, or operator-supplied data where the operator does not control analysis or publication. If no independent method can link a persisted item to its preceding interaction, Gate B is NOT VALIDATED: EVIDENCE UNAVAILABLE, not falsified.
5.5 Gate C · symmetric same-user test
At least 1,000 consenting users must supply overlapping-period data from one conversational AI history and at least two behavioural streams, such as Google Search, YouTube Search, YouTube Watch, browser history or shopping search.
- Facts are extracted from every surface independently before any comparison.
- Two human coders validate extraction; reliability must reach Cohen’s κ or Krippendorff’s α ≥ 0.80, with disagreements adjudicated. Coders judging equivalence are blind to source surface where feasible.
- Primary endpoint: explicit match. A fact counts as recovered only if the same proposition is explicitly present in the other surface. A search for wheelchair-accessible hotels does not recover “my mother cannot walk more than ten minutes”. Model inference is reported only as exploratory.
- Three counts are published per user: AI-unique, behaviour-unique and shared. A study reporting only one direction cannot decide the gate.
| Result, preregistered paired test | Gate C state |
|---|---|
| AI-unique significantly exceeds behaviour-unique | PASSED |
| Behaviour-unique significantly exceeds AI-unique | FALSIFIED |
| No significant difference | INCONCLUSIVE |
Gate C tests structural distinctness, not growth. A correctly designed study on early-2026 data might already pass it; that would be a baseline structural finding, not validation of the forecast. Growth is tested only by Gate A.
5.6 Evidence states
Each gate ends in one of four states: PASSED, FALSIFIED (qualifying evidence contradicts the threshold), INCONCLUSIVE (qualifying evidence neither passes nor contradicts), or NOT VALIDATED: EVIDENCE UNAVAILABLE. Missing evidence is never converted into falsification, and never into confirmation.
5.7 Verdict matrix
| Evidence state | Verdict |
|---|---|
| A, B and C passed | FULLY VALIDATED |
| A and C passed; B failed or unavailable | CORE FORECAST VALIDATED |
| A passed; C unavailable or inconclusive | SCALE FORECAST VALIDATED; DISTINCTNESS UNVERIFIED |
| A inconclusive | SCALE FORECAST INCONCLUSIVE |
| A falsified; direct plus connected meets PASSED | CHANNEL SUBSTITUTION: ORIGINAL FORECAST NOT VALIDATED |
| A falsified otherwise | SCALE FORECAST FALSIFIED |
| C passed; A not passed | STRUCTURAL OBSERVATION CONFIRMED; FORECAST NOT VALIDATED |
| C falsified | DISTINCT-SURFACE CLAIM FALSIFIED |
| B passed alone | SYSTEM-DERIVED PERSISTENCE CONFIRMED |
| No qualifying evidence by 31 December 2031 | NOT VALIDATED: EVIDENCE UNAVAILABLE |
Any Gate A qualifier, including INTENSIVE-USER CONCENTRATED, automatically attaches to every verdict that relies on Gate A.
Gate A carries the forecast. Each gate’s state is always published alongside the overall verdict.
5.8 Interim review · 31 December 2028
Gate A cannot be assessed at the interim, because its follow-up window opens only in September 2029. The interim review records three things: whether a qualifying baseline has been built and archived, the state of Gate B, and the state of Gate C. Interim findings are non-binding and appended as a separate dated block.
5.9 No post-hoc adjustment
After 24 September 2026, no threshold, window, taxonomy, fact unit or verdict rule will be relaxed. A hypothesis suggested by later data will be recorded as a new, separate forecast and tested prospectively, never as validation of this one.
Important note
This is a dated, falsifiable research forecast, not an accusation. It alleges no unauthorised or unlawful data collection by Google, Meta, OpenAI or any other operator, and it describes product features as their operators document them. Several founding sources are preprints and should be read as preliminary. Nothing here is legal advice. Validation updates will be added as separate dated blocks; this entry will not be edited after publication.
Lock line
Google और Meta ने दशकों में इंसानी behaviour की विशाल digital data layer बनाई।
AI ने उसके साथ एक नया layer जोड़ा: इंसान machine को अपना context सीधे बताने लगा।
सवाल यह नहीं कि AI के पास data होगा या नहीं। सवाल यह है कि अगले पाँच साल में इंसान AI को अपने बारे में कितना ज़्यादा बताएगा।
Behavioural signals + direct disclosure. Human data is the fuel.
बताते हम थे बुझाते वो थे
दिखाते हम थे समझाते वो थे
इस बताने बुझाने दिखाने और समझाने में
वो मेरे अक्स में शामिल हो गए जाने अनजाने में
— Ankur Grover
References
- Zaman, S. M. M., & Garimella, K. (2026, 22 May). Inferential Privacy Leakage in Anonymized Conversational AI Logs. arXiv:2605.23820 (preprint). arxiv.org/abs/2605.23820
- Zaman, S. M. M., & Hoque, M. M. (2026, September). Vulnerabilities in Personalization: Assessing Health Privacy Risks in ChatGPT Logs and Memory. arXiv:2609.14697 (preprint). arxiv.org/abs/2609.14697
- Dash, A., Das, S., Kirsten, E., Wu, Q., Karnam, S. K., Gummadi, K. P., Holz, T., Zafar, M. B., & Zannettou, S. (2026). The Algorithmic Self-Portrait: Deconstructing Memory in ChatGPT. Proceedings of the ACM Web Conference 2026, 3471–3482. doi.org/10.1145/3774904.3792671
- Google India Blog (2026, 14 April). Personal Intelligence launches in the Gemini app in India. blog.google
- OpenAI (2026, 4 June). Dreaming: Better memory for a more helpful ChatGPT. openai.com
Access dates, archive snapshots and source status: see Source Archive Manifest.
Ankur Grover
Observe • Validate • Document
Global Observation Archive · bhriguaiastro.com